
Enterprise Synthetic Data Pipelines have quietly become the backbone of how major AI models get trained — and for B2B SaaS teams building on top of those models, understanding how that data was produced is no longer optional.
The internet’s supply of usable, high-quality text has a hard ceiling. Epoch AI estimates roughly 300 trillion tokens of high-quality public text exist online, and frontier models are already consuming a meaningful share of that in single training runs. Microsoft addressed this directly by training its Phi-4 model on 400 billion synthetic tokens rather than relying solely on scraped web data. Market analysis of dedicated synthetic data services for enterprise AI projects growth from roughly $420 million in 2025 to $2.27 billion by 2031, a 32.77% compound annual growth rate — a trajectory that reflects how fast this has moved from a research curiosity to core AI infrastructure that enterprise buyers now budget for explicitly.
This guide breaks down what Enterprise Synthetic Data Pipelines actually are, the real technical risk they carry if built carelessly, and how B2B SaaS teams should approach building or buying one — grounded in peer-reviewed research rather than vendor marketing claims.
Why Enterprise Synthetic Data Pipelines Matter in 2026
Three forces explain why Enterprise Synthetic Data Pipelines moved from a niche technique to mainstream AI infrastructure this year.
First, the data scarcity problem is structural, not temporary. High-quality, unique training text on the public internet is finite, and models keep growing while the underlying pool of fresh human-generated text does not grow at the same rate. Synthetic data fills that gap directly, generating additional training examples that mimic the statistical properties of real data without requiring new human-authored source material.
Second, privacy and regulatory pressure make synthetic data attractive for a second, unrelated reason. Regulators in multiple jurisdictions have started explicitly recommending synthetic or anonymized data for AI systems handling sensitive information, and the EU AI Act’s high-risk AI obligations, effective August 2026, increase the documentation burden around any data used to train systems that affect real people — synthetic data sidesteps some of that exposure when built correctly.
Third, the tooling matured fast enough that this is no longer a research-lab-only capability. Every major cloud provider now offers synthetic data generation tooling, and dedicated synthetic data vendors have attracted serious acquisition interest, signaling that buyers see this as durable infrastructure rather than a passing trend. That maturity curve matters for B2B SaaS teams specifically, since it means the barrier to standing up a first pipeline has dropped significantly even for companies without a dedicated data science function. For the broader context on how enterprises are proving value from AI investment generally, see our guide on generative AI value measurement.
What Enterprise Synthetic Data Pipelines Actually Produce
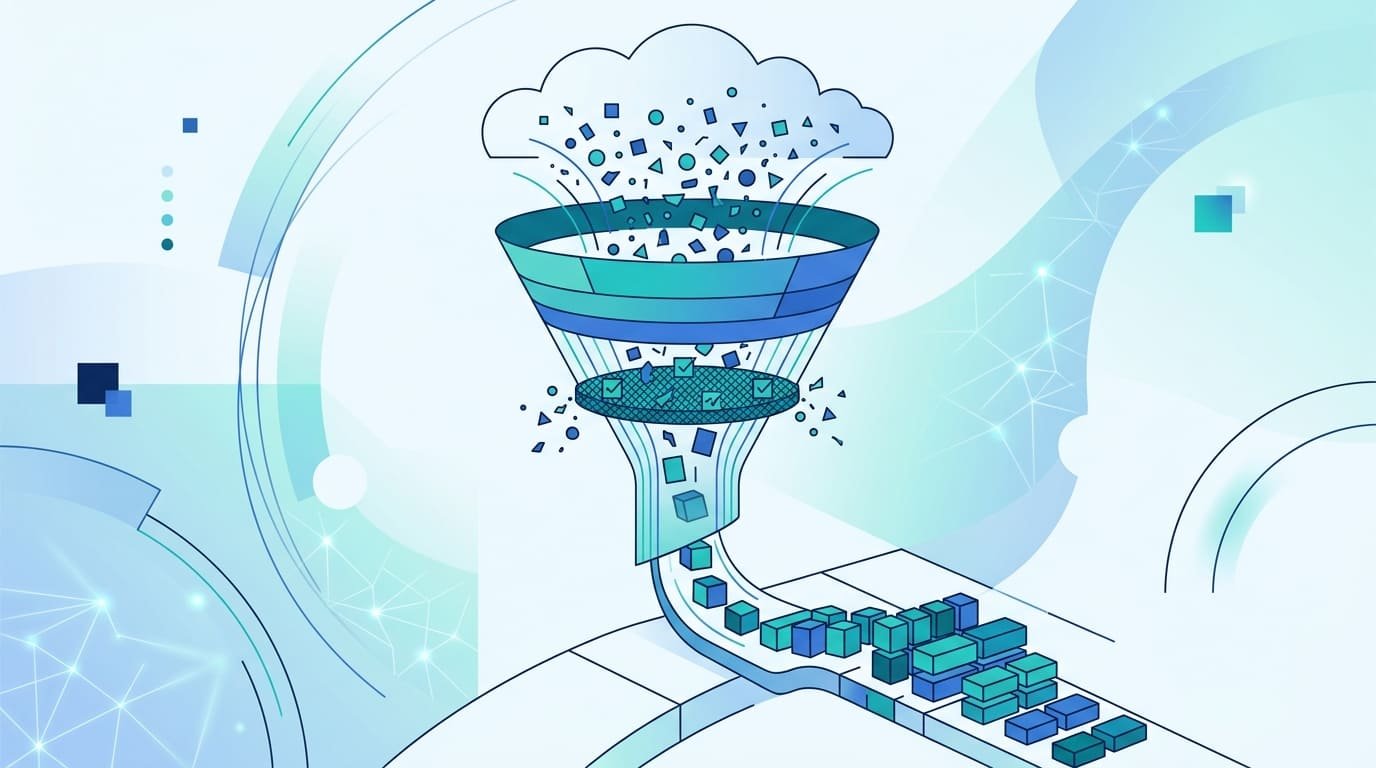
Enterprise Synthetic Data Pipelines generate artificial data — text, structured records, images, or tabular data — designed to statistically resemble real data without containing any actual real-world records. A pipeline typically includes a generation stage (using a model or simulation to produce candidate data), a validation stage (checking the output against quality and diversity criteria), and a filtering stage (discarding low-quality or degenerate examples before they reach a training set).
The output isn’t meant to replace real data entirely in most mature deployments. Instead, Enterprise Synthetic Data Pipelines typically supplement real data — filling gaps where rare events are underrepresented, generating privacy-safe test and development datasets, or producing domain-specific training examples a company can’t ethically or legally collect at scale from real users. A well-designed pipeline treats synthetic generation as an extension of an existing data strategy, not a substitute for having one.
The Real Risk: Model Collapse in Enterprise Synthetic Data Pipelines
This is the part of Enterprise Synthetic Data Pipelines that gets the least attention relative to how damaging it can be if ignored. A peer-reviewed study published in Nature found that training AI models recursively on AI-generated data causes progressive quality degradation — a phenomenon the researchers termed model collapse, and one that has since drawn significant attention across the machine learning research community. After repeated generations of training on synthetic outputs, models lose the tails of the original data distribution: rare events vanish, and outputs converge toward a narrow, repetitive mean.
The risk compounds at an ecosystem level, not just within a single company. If one organization trains a model on synthetic data and publishes its outputs, and another organization scrapes those outputs to generate its own synthetic training data, both models degrade — a feedback loop the same research flagged as already underway across parts of the public internet.
For B2B SaaS teams, this has a direct practical implication: Enterprise Synthetic Data Pipelines that recursively train on their own prior outputs, generation after generation, without fresh real-world data anchoring the distribution, are building toward a quality cliff that often isn’t visible until it’s already significant. A model that looks fine on aggregate benchmark scores can already be quietly losing its ability to handle rare or unusual inputs — exactly the cases where reliability matters most in a production B2B product.
How to Build Enterprise Synthetic Data Pipelines That Avoid Model Collapse
A handful of practical safeguards separate Enterprise Synthetic Data Pipelines that hold up over time from ones that quietly degrade.
- Always anchor to a real-data baseline. Never train exclusively on synthetic data across multiple generations — maintain a consistent proportion of verified real-world data in every training cycle to preserve the tails of the original distribution.
- Track provenance rigorously. Know exactly which portion of any training set is synthetic, which generation of the pipeline produced it, and which underlying model generated it. Our guide to AI model risk management covers the broader risk classification this data provenance work feeds into.
- Measure distributional diversity, not just volume. A pipeline producing large volumes of synthetic data that’s statistically narrower than real-world data is optimizing for the wrong metric; diversity and rare-event representation matter more than raw record count.
- Validate against held-out real data continuously. Testing model performance against a real, held-out dataset — not just synthetic validation data — is the most reliable early warning sign of drift toward collapse.
- Treat synthetic data governance as part of your broader evaluation framework. Our AI governance evaluation metrics guide covers how to build the kind of ongoing measurement discipline synthetic data pipelines require.
What Maturity Actually Looks Like
Because Enterprise Synthetic Data Pipelines are relatively new territory for most B2B SaaS teams, a rough maturity picture helps calibrate where a given pipeline actually stands.
At the low end, teams generate synthetic data ad hoc, with no consistent provenance tracking and no held-out real-data validation — essentially treating synthetic generation as a black box that produces “more data” without instrumenting what that data actually looks like statistically. In the middle, teams track which datasets are synthetic and validate periodically against real data, but the process is manual and inconsistent across different model training runs. At the mature end, provenance tracking, real-data anchoring ratios, and distributional diversity checks are built into the pipeline itself as automated gates, catching drift before a degraded dataset ever reaches a production training run.
Most B2B SaaS teams experimenting with synthetic data today sit in the low or middle tier. Reaching the mature end doesn’t require a research team — it requires treating the validation and provenance steps as non-negotiable pipeline stages rather than optional add-ons applied only when someone remembers to check.
Who Should Own Synthetic Data Strategy Inside a SaaS Organization
This work tends to stall when it sits entirely with whichever engineer first proposed using synthetic data, with no broader governance or product involvement. Engineering typically owns the generation and validation pipeline itself. Data or ML governance functions, where they exist, should own the provenance tracking and collapse-risk monitoring specifically, since this requires ongoing measurement discipline rather than a one-time build. Product and compliance stakeholders need visibility into which customer-facing AI features depend on synthetic training data, since that dependency has downstream implications for both quality and regulatory documentation.
The structure that tends to work is a small, named group — usually an ML engineering lead paired with whoever owns broader AI governance — that reviews pipeline health and real-data anchoring ratios on a recurring cadence, rather than treating synthetic data generation as a set-and-forget utility once it’s built.
Enterprise Synthetic Data Pipelines: Build vs. Buy
Most B2B SaaS teams face a build-versus-buy decision once they’ve decided synthetic data belongs in their training or testing strategy.
| Building In-House | Using a Vendor Platform | |
|---|---|---|
| Speed to first use | Slower — requires assembling generation, validation, and filtering stages | Faster — most platforms ship with built-in quality checks |
| Domain specificity | Higher — tuned precisely to your data patterns | Variable — depends on vendor’s domain coverage |
| Model collapse safeguards | Your responsibility to implement | Often built in, but varies significantly by vendor |
| Ongoing cost | Engineering time, ongoing maintenance | Subscription or usage-based fees |
Teams with a narrow, well-understood domain and in-house ML expertise often get more value building in-house, since domain-specific tuning tends to matter more than general-purpose polish for niche use cases. Teams needing broad coverage quickly, or without dedicated ML infrastructure staff, typically get to production faster with a vendor platform — provided that platform can demonstrate its own collapse-prevention safeguards during evaluation, not just after a contract is signed.
Common Mistakes When Implementing Enterprise Synthetic Data Pipelines
- Treating synthetic data as a free, unlimited resource. Every generation of synthetic data carries compounding quality risk; volume without quality control accelerates collapse rather than avoiding scarcity.
- Skipping provenance tracking because it feels like overhead. Without knowing which data is synthetic and which generation produced it, diagnosing quality degradation after the fact becomes nearly impossible.
- Validating only against synthetic benchmarks. A pipeline that only checks its own synthetic output against other synthetic output can’t detect drift away from real-world data patterns.
- Ignoring the compliance angle entirely. Synthetic data can reduce certain privacy risks, but it doesn’t eliminate documentation obligations — our AI data residency compliance guide covers adjacent data-handling obligations that still apply.
- Assuming a vendor’s synthetic data is automatically safe. Not every vendor platform actively guards against model collapse; this needs to be a specific, verified question during evaluation, not an assumption based on marketing claims alone.
Strategic Outlook: Enterprise Synthetic Data Pipelines as B2B SaaS Infrastructure
From a product and growth standpoint, Enterprise Synthetic Data Pipelines deserve the same architectural seriousness as any other core infrastructure decision, not a side project handed to whichever team has spare capacity. SaaS companies building AI features that depend on quality training or test data are, whether they realize it or not, making a synthetic-data-strategy decision by default the moment they start supplementing real data with generated examples.
It’s worth staying grounded here too: synthetic data is a powerful supplement, not a wholesale replacement for real-world data collection. Teams chasing pure cost or speed advantages by minimizing real data collection entirely are the ones most exposed to the collapse risk documented in peer-reviewed research. The goal is using synthetic generation to extend and fill gaps in a real-data foundation, not to eliminate the need for that foundation altogether.
Practical next steps for SaaS product and engineering teams:
- Audit any AI features currently trained or fine-tuned on synthetic data for provenance tracking and real-data anchoring today, not after a quality issue surfaces.
- Build synthetic data quality checks into existing model evaluation cadences rather than treating them as a separate, one-off review. Our LLM security guide covers instrumentation patterns that extend naturally to data pipeline monitoring.
- When evaluating vendor synthetic data platforms, ask directly how they measure and prevent model collapse — treat vague answers as a disqualifying signal, not a minor gap.
- Revisit synthetic data strategy quarterly as both the underlying research and available tooling continue to evolve quickly.
For the primary research this guide is grounded in, see Shumailov et al.’s peer-reviewed study on AI model collapse, published in Nature.
Frequently Asked Questions
What are Enterprise Synthetic Data Pipelines? Systems that generate artificial data statistically resembling real data — through generation, validation, and filtering stages — used to supplement real-world data for training or testing AI models.
What is model collapse, and why does it matter? Model collapse is a documented phenomenon where AI models trained recursively on AI-generated data progressively lose the diversity and rare-event representation of the original data distribution, converging toward degraded, repetitive outputs over successive generations.
Does synthetic data eliminate data privacy compliance obligations? No. Synthetic data can reduce certain privacy exposures, but it doesn’t eliminate documentation and provenance obligations, particularly under frameworks like the EU AI Act that require traceability for high-risk AI systems affecting real people.
Should we build our own synthetic data pipeline or use a vendor? It depends on domain specificity and in-house ML capacity — narrow, well-understood domains with dedicated ML expertise often favor building in-house, while broader coverage needs typically move faster with a vendor platform that has verified collapse-prevention safeguards.
How much of a training set should be synthetic versus real data? There’s no universal ratio, but maintaining a consistent, meaningful proportion of verified real-world data in every training cycle is the most reliable safeguard against the distributional drift that leads to model collapse.
How do we know if our pipeline is already showing signs of collapse? Watch for outputs converging toward repetitive, less diverse patterns over successive generations, and for degraded performance on rare or edge-case inputs specifically — these are typically the first measurable signs, well before overall benchmark scores show an obvious decline, and they’re worth checking on a recurring schedule rather than only after a customer reports a problem.
Conclusion
Enterprise Synthetic Data Pipelines have become genuine AI infrastructure in 2026, not an experimental workaround for data scarcity, and the peer-reviewed research on model collapse makes clear that building one carelessly carries a real, compounding quality risk. B2B SaaS teams that anchor their pipelines to real data, track provenance rigorously, and validate continuously against held-out real datasets will avoid the quality cliff that catches teams treating synthetic data as an unlimited, risk-free resource.
None of this requires solving the entire pipeline at once. Starting with a provenance audit of any AI feature currently trained on synthetic data, adding a held-out real-data validation step to the next training cycle, and building the ownership structure to keep that discipline going are each achievable within a single quarter — and each step reduces the odds of a quality problem surfacing only after it’s already expensive to unwind. If you’re ready to assess where your own AI training and testing pipelines stand, start with that provenance audit this quarter and build your safeguards around what it finds.
About the Author
Meet Waqas Raza — a B2B Digital Growth Specialist writing for Vitalora Life, with a background in Finance and 20 years scaling technical SaaS architectures. Waqas shares practical, data-backed frameworks on AI governance, SaaS growth, and turning AI investment into measurable outcomes.